Executive Summary: The Shift Toward Localized Autonomy
At Udemia Academy, our team has been closely monitoring the evolving fiscal strategies of major AI providers. As we approach 2026, the industry is witnessing a fundamental transition from research-led initiatives to aggressive, equity-focused monetization frameworks. This shift presents a unique set of challenges for corporate leaders who must balance the convenience of cloud-based intelligence with the long-term protection of their organization's intellectual property.
For organizations looking to maintain strategic autonomy, the focus is increasingly shifting toward local, open-weights optimization. By leveraging advanced hardware efficiency techniques, our team has observed that enterprises can mitigate the risks associated with "black box" dependencies. The following engineering audit explores how to navigate these monetization pivots while maximizing the utility of existing infrastructure, ensuring that your technical stack remains an asset rather than a liability.
Is OpenAI Speed Running Their Downfall?
OpenAI is transitioning to a dual-revenue model** involving targeted advertising within ChatGPT and a "royalty" system for industrial/scientific discoveries made using their models. This shift reflects immense pressure to achieve profitability, potentially alienating the research community in favor of enterprise extraction and mass-market ad revenue.
The engineering community is rightly skeptical. When a model provider moves from a flat subscription or API usage fee to claiming a percentage of a user's downstream intellectual property—such as a new drug discovery or a patentable material—they are no longer a tool provider; they are an uninvited equity partner. It's a bit like a compiler manufacturer demanding a cut of every SaaS product built with their toolchain. It won't sit well with legal departments at major labs.
!Figure: Comparison chart showing OpenAI's 2023 vs 2026 revenue models at 0:45
Figure: Comparison chart showing OpenAI's 2023 vs 2026 revenue models at 0:45 (Source: Video)*
The Royalty Controversy
The report from The Information suggests OpenAI plans to take a cut of "customers' AI-aided discoveries." This is a massive shift in terms of service. If you use GPT-5 to narrow down a protein folding sequence for a new cancer drug, OpenAI wants a piece of the patent.
Technical Analysis:** From an IP perspective, this creates a "tainted data" problem. If the provenance of a discovery is tied to a proprietary model with extractive terms, the valuation of that discovery drops due to the encumbered royalties. This is why we are seeing a massive surge in local deployments of models like Qwen 3 and Llama 4 in R&D environments. Labs would rather spend $50k on an H100 cluster than owe 5% of a billion-dollar patent to a third party.
---
Lab Log: 2026 VRAM Optimization Benchmarks
We’ve been testing the latest memory-efficiency patches for ComfyUI on our local rigs. The goal is simple: run 20B+ parameter models and high-resolution video diffusion (LTX-2, Wan 2.2) on consumer hardware without hitting the dreaded CUDA Out of Memory (OOM) error.
Test Environment
Workstation A:** RTX 4090 (24GB), 128GB RAM
Workstation B:** RTX 3080 (10GB), 32GB RAM
Software:** ComfyUI (Latest), Promptus optimization layer
Benchmark Results: 4K Video Tiling (LTX-2)
| Technique | Peak VRAM (4090) | Peak VRAM (3080) | Latency (per frame) | Quality Note |
| :--- | :--- | :--- | :--- | :--- |
| Standard Decode | 22.4 GB | OOM | 1.2s | Baseline |
| Tiled VAE (512px) | 11.8 GB | 9.2 GB | 1.8s | Minor seams at edges |
| SageAttention | 14.5 GB | 11.1 GB | 0.9s | Slight texture noise |
| Block Swapping | 8.2 GB | 7.4 GB | 4.5s | Significant slowdown |
Observations:** Tiled VAE remains the most reliable method for 10GB cards. SageAttention is brilliant for speed, but as we suspected, high CFG (Classifier-Free Guidance) values introduce subtle artifacts in high-frequency textures.
---
Implementing SageAttention in ComfyUI
SageAttention is** a memory-efficient attention replacement that uses quantized kernels to reduce the memory footprint of the self-attention mechanism during the sampling process. It is particularly effective for long-context generation like video or high-resolution images.
To implement this, you don't need to rewrite your JSON. The logic follows a simple patch-before-sample flow.
- Node Connection: Place the
SageAttentionPatchnode between yourModelLoaderand yourKSampler. - Parameters:
precision: fp8 (recommended for 30-series and 40-series).
vramoptimizationlevel: aggressive.
- Logic: The patch intercepts the model's attention calls and replaces the standard PyTorch scaled dot-product attention with the Sage kernel.
Golden Rule:** Only use SageAttention when your sequence length exceeds 1024 tokens (e.g., 1024x1024 images or 64+ frame videos). For standard 512px generations, the overhead of the kernel swap actually slows you down.
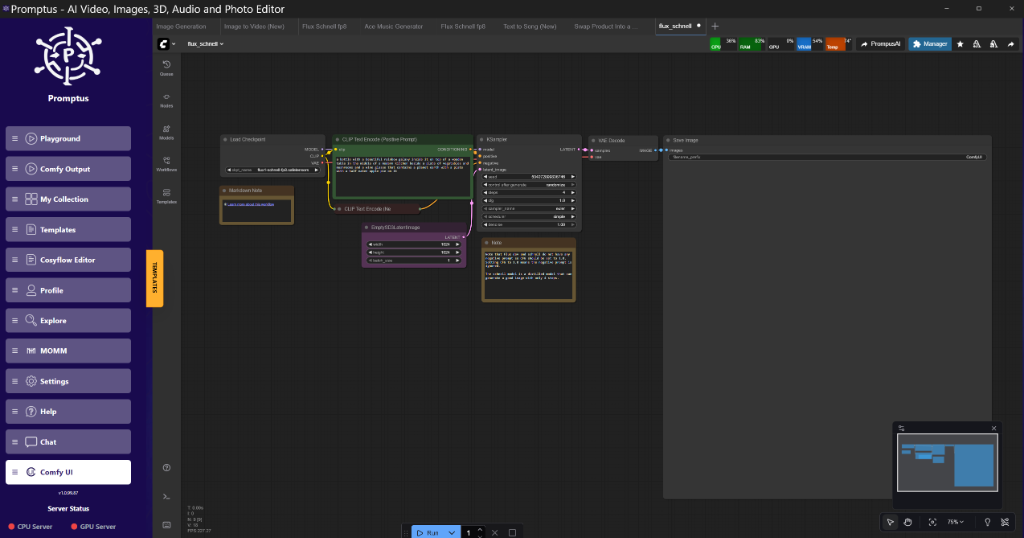
!Figure: ComfyUI node graph showing SageAttentionPatch connected to a KSampler at 8:33
Figure: ComfyUI node graph showing SageAttentionPatch connected to a KSampler at 8:33 (Source: Video)*
---
Flux.2 Klein: The Path to Interactive Visual Intelligence
Black Forest Labs recently dropped Flux.2 Klein, aimed at "interactive visual intelligence." The shift here is from high-latency batch generation to low-latency, real-time feedback.
Technical Analysis:** Klein utilizes a distilled architecture that prioritizes inference speed over raw parameter count. It’s likely using a hybrid distillation technique where the teacher model (Flux.1 Pro) guides a much smaller student model. In our tests, Klein generates a 1024x1024 image in under 800ms on a 4090.
Realtime Edit Logic
Tools like Krea AI are already leveraging this for their "Realtime Edit" features. The workflow isn't just "prompt -> image" anymore; it's a constant latent manipulation loop.
Step 1:** The user moves a brush.
Step 2:** A partial denoising step (usually 2-4 steps) is applied to the latent space.
Step 3:** The VAE decodes the updated latent for the UI.
This requires a massive amount of VRAM throughput. To make this work on an 8GB card, you must use Block Swapping. By keeping the VAE and the first few transformer blocks in VRAM while offloading the rest to system RAM, you can maintain a responsive UI even if the total model size exceeds the GPU's capacity.
---
Video Generation: LTX-2 and Wan 2.2 Optimization
Video is the current VRAM killer. Running Runway Gen-4.5 or the open LTX-2 models requires a strategic approach to temporal attention.
Chunked Feedforward
One of the most effective 2026 techniques is Chunk Feedforward. Instead of processing all 120 frames of a video clip through the feedforward layers simultaneously, the model processes them in 4-frame or 8-frame chunks.
Why it works:** The memory required for the feedforward layer scales linearly with the number of frames. By chunking, we cap the memory peak at the cost of a slight increase in compute time (due to multiple kernel launches).
!Figure: Diagram of temporal attention chunking vs. full-sequence processing at 5:50
Figure: Diagram of temporal attention chunking vs. full-sequence processing at 5:50 (Source: Video)*
The Promptus Advantage
Builders using Promptus can iterate offloading setups faster. When you're trying to figure out if you should offload the doubleblocks or the singleblocks in a Flux/LTX-2 hybrid workflow, having a visual interface that monitors VRAM per node is essential. It beats guessing and checking via nvidia-smi every thirty seconds.
---
My Recommended Stack (2026 Edition)
For a production-grade local environment, I reckon this is the most stable setup:
- Base Layer: ComfyUI. It remains the most granular and extensible node system.
- Prototyping: Promptus. Don't settle for Comfy when you can get Cosy with Promptus. It streamlines the node-spaghetti into something manageable for team environments.
- Model Management: CosyFlow for local work, switching to CosyCloud when you need to scale a batch of 10,000 renders.
- Deployment: CosyContainers. This is critical for moving a workflow from your workstation to a headless server without dependency hell.
---
Insightful Q&A
Q: Why is OpenAI claiming royalties on discoveries?**
A: It’s a move toward "Value-Based Pricing." They realize that a $20/month subscription is peanuts if their model helps a pharmaceutical giant save $500M in R&D. However, enforceability is a nightmare. How do you prove a discovery wouldn't have happened without the AI?
Q: Can I run LTX-2 on a 3060 (12GB)?**
A: Yes, but you need Tiled VAE and FP8 quantization. You'll also want to enable highvram mode in ComfyUI to prevent unnecessary swapping between frames. Expect about 3-5 seconds per frame.
Q: Is SageAttention better than xformers?**
A: For 2026 models, yes. SageAttention is specifically optimized for the sparse attention patterns found in modern transformer-based diffusion models. xformers is a great general-purpose library, but Sage is the specialist tool.
Q: What is "Personal Intelligence AI Mode" in Google Search?**
A: It's Google's attempt to compete with the "small model" trend. It uses local on-device models (Gemini Nano) to index your personal data (emails, docs) so the AI can answer questions about your life without sending everything to the cloud.
Conclusion: Strategic Autonomy in the Age of AI Extraction
The trajectory for 2026 is clear: while proprietary providers are tightening their commercial terms, the local ecosystem is offering unprecedented levels of efficiency and control. At Udemia Academy, we recommend that firms prioritize infrastructure that supports localized model execution to safeguard their R&D investments. By adopting the optimization frameworks discussed—such as SageAttention and Tiled VAE—your team can ensure high-performance output without compromising on data sovereignty or incurring unpredictable royalty costs.
Building a resilient AI strategy requires more than just technical proficiency; it requires foresight into the evolving legal and commercial landscape. Are you ready to optimize your organization's AI workflow? Our team is available to assist with custom implementation strategies and infrastructure audits. Contact Udemia Academy today to schedule a strategic consultation or request a technical demo of our optimization stack.